

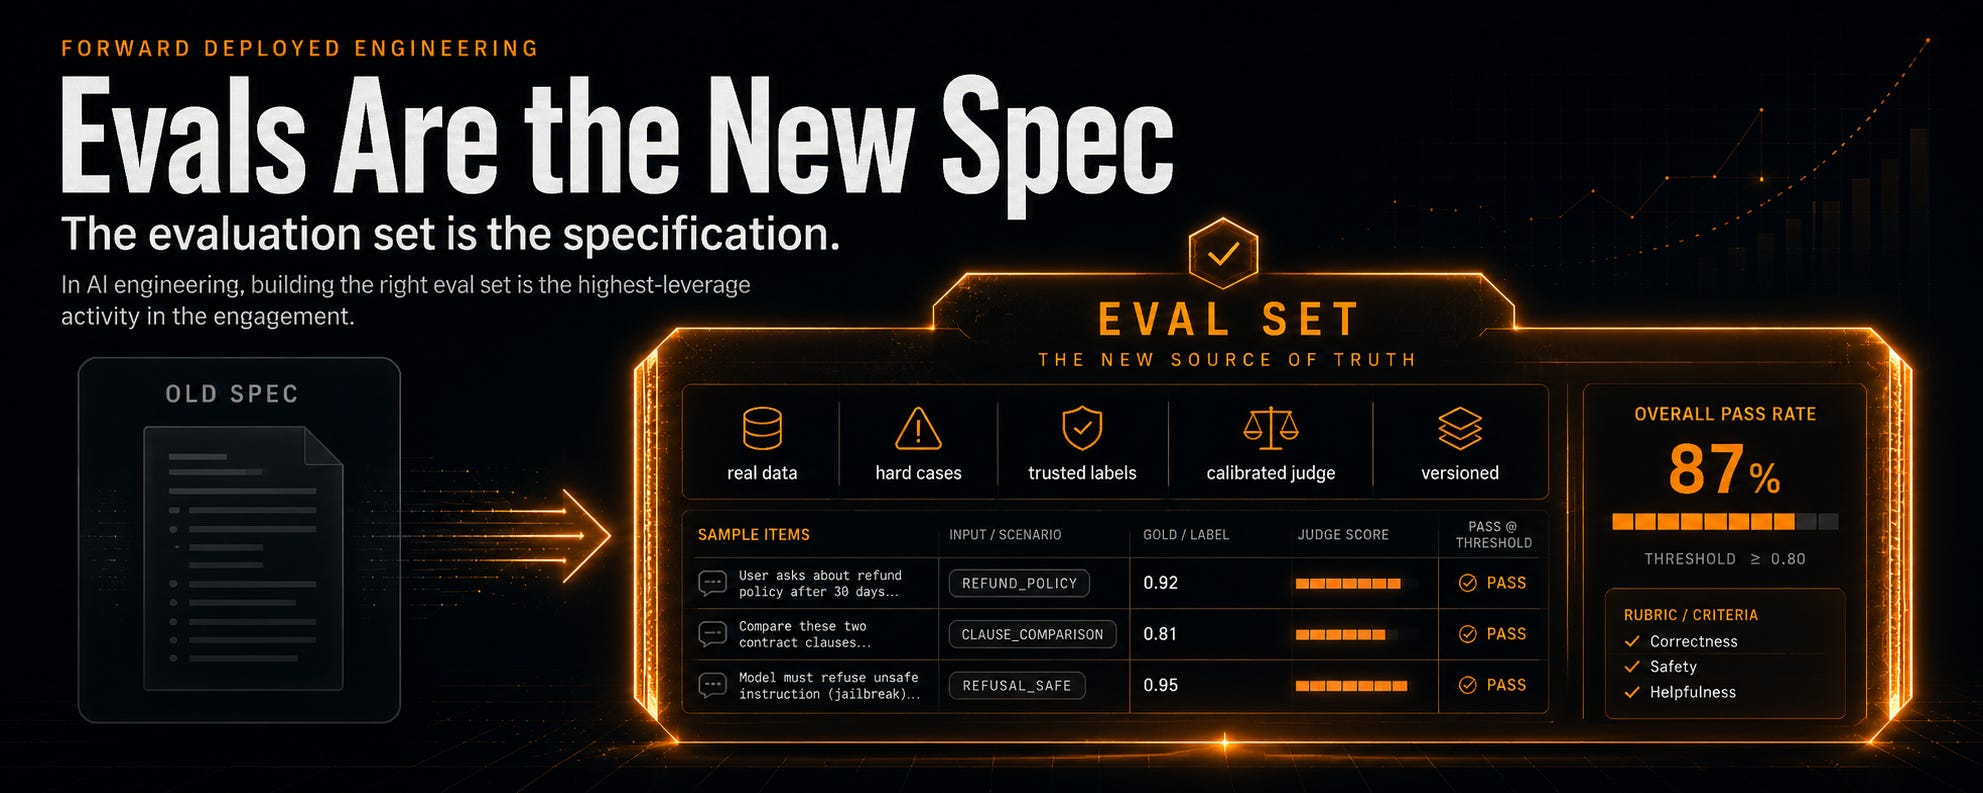
In traditional software, the specification is a document. Engineers write code that satisfies it, tests check the match, and the spec is the source of truth. In AI engineering, the specification is the evaluation set: a collection of input-output pairs, sometimes with rubrics, that defines what good performance looks like. The model is the implementation, judged against the eval set. That sounds like a small change, but it inverts the engineering process.
Why does it matter so much for deployment work? Because the eval set decides whether validation succeeds, and validation decides whether the engagement succeeds. If the eval set tests for things the customer doesn’t care about, or omits things they do, a system that passes will still fail in production. Hamel Husain has been blunt about the pattern: failing AI products almost always share one root cause, the absence of a working evaluation system.
What a working eval set looks like
Built from real customer data, not synthetic. Synthetic data lies: it’s cleaner, narrower in distribution, and free of the edge cases real data spits out. The data-access fight you have to have is part of the work; ducking it to ship faster will cost you the engagement.
Big enough for signal, small enough to iterate. One hundred to a few hundred examples for the first version. Ten thousand is too many: the grading cost is high and the iteration cycle becomes slow enough that the team stops looking at results.
Bespoke to the customer’s outcome. Public benchmarks help you pick a base model. They tell you nothing about whether your specific system, for this specific customer, will produce the business outcome they signed up for.
Weighted with hard cases. The customer’s domain experts know which cases are hard, so ask them. A system that passes the easy cases and fails the hard ones is not ready.
Labeled by people the customer trusts. Vendor-side labels have no credibility with the customer. The labeling interface should let their experts grade two to five examples a minute, or the labeling won’t get done.
Versioned. The eval set evolves, and the team needs to know whether a score improvement came from a better system or a moved bar.
LLM-as-judge, calibrated or worthless
The hardest part is the middle layer: cases where the right answer can’t be expressed as an assertion but human grading doesn’t scale. The standard tool is the LLM-as-judge, a separate model call that grades outputs against a rubric. It works, with caveats. Judges carry predictable position, verbosity, and self-enhancement biases, and they only earn their keep when calibrated against human labels on your own data. Without calibration you’re laundering noise: the judge produces scores, the team acts on them, and the scores have an unknown relationship to the customer’s actual quality bar.
The calibration is tedious and simple. Have the customer’s experts label fifty to a hundred outputs, have the judge label the same set, and compute agreement. Above roughly eighty percent, you have a working judge for this rubric on this data. Below it, iterate on the rubric or the prompt until agreement climbs, and recalibrate every time the underlying model changes. Expect what Shreya Shankar’s research calls criteria drift: practitioners cannot fully define eval criteria up front. The first rubric is always wrong, and grading real outputs is what crystallizes it. Draft, grade fifty examples with the customer’s expert, revise, repeat.
From gate to flywheel
Evals do their best work not as a gate but as the feedback signal the entire build cycle climbs against. OpenAI’s John Deere voice-agent engagement is the canonical illustration. The FDE team built an eval set with the customer, labeled by people who actually understood farming. The model wasn’t good enough, so the data went back to the research team; the improved model cleared the bar, and the customer signed off on production in time for the growing season. Without the eval set, the project would have shipped a system that disappointed the farmers in the field.
One concrete recommendation: after scoping, spend the first week of validation building the eval set. Don’t write production code or stand up the integration yet. Build the evals, run the baseline, and show the customer the gap between where the system is and the threshold they’re paying for. If the gap is small, the engagement is short. If it’s large, you now share an honest understanding of the work involved, and you’ve saved yourselves weeks of misaligned expectations and the late-stage scope disputes that destroy engagements.
In one contract-review deployment I ran, the eval set grew from 42 cases to 131 over three months, with the customer’s deputy general counsel adding every case that surprised her, labeled the same day. By month three the eval set had become the firm’s internal reference for what good meant in contract review. We hadn’t planned for that. It became the most valuable artifact of the engagement.
Want the full playbook, with the templates, the interview transcripts, and the week-one checklist? It’s all in my book Forward Deployed AI Engineering: A Working Guide to the Hottest Job in Software, available on Amazon: [Amazon link]